01
Context
Finding relevant information across images, tables, PDFs, and text takes more than a keyword index. The project, initially conceived as the technical foundation for a mobile experience called MAYbe Here, gradually refocused on the search engine itself — a pipeline able to cross-reference several forms of information from a text or visual query.
02
Multimodal architecture
The pipeline is organized into independent modules, from source ingestion through to result delivery.
- Ingestion and normalization of heterogeneous sources
- Persistent storage in a Vector Lakehouse
- Visual and text embeddings
- Local semantic arbitration
- Multi-pass hybrid search and confidence scoring
- Search API and demo interface
03
Vector Lakehouse
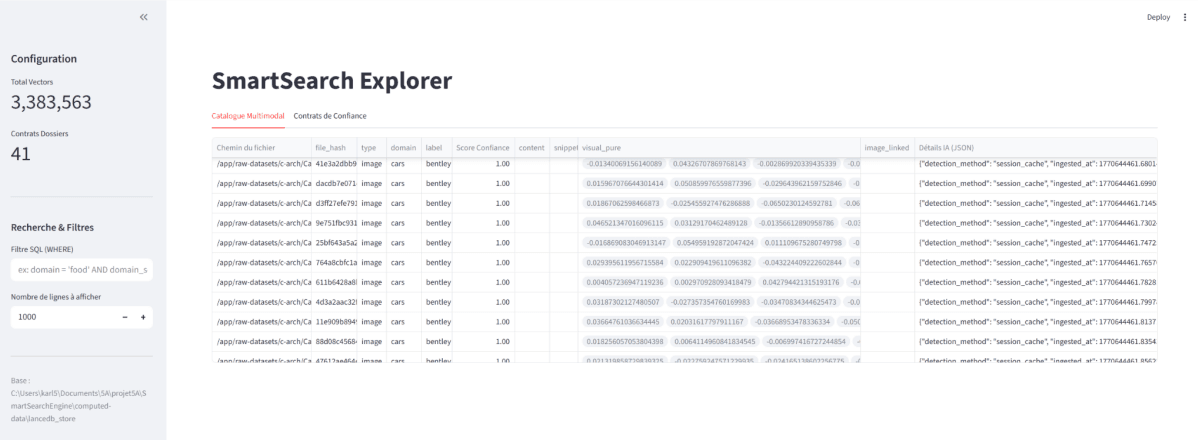
Storage relies on LanceDB and Apache Arrow to unify vectors, metadata, and structured data in a single persistent store. This replaces an initial approach based on in-memory vector indexes, which was too RAM-dependent for large volumes. Images and text are projected into a shared vector space with CLIP, enabling search by visual, textual, or combined similarity.
04
Multimodal ingestion
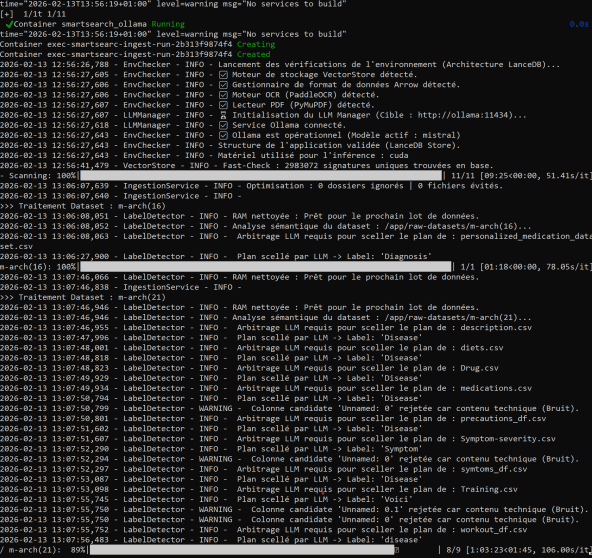
The engine accepts several source types — image folders, CSVs and structured data, PDFs, and plain text. Hierarchical scanning detects changes and limits re-indexing to items that actually changed; processing is done in streaming batches to keep memory usage under control on large corpora.
- Change detection and incremental re-indexing
- Streaming, batch-based processing
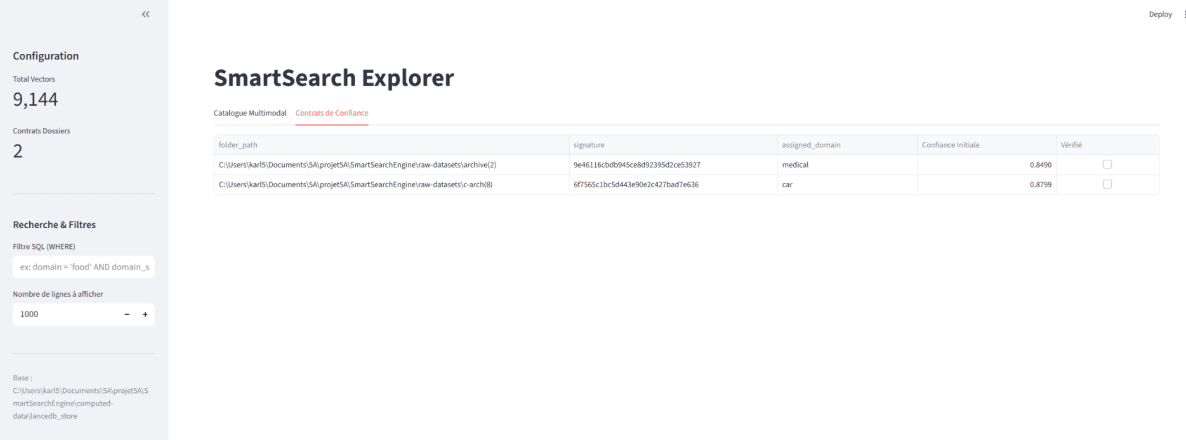
- Trust contract and assigned domain per ingested folder
05
Local AI and restraint
The LLM is not applied systematically to every piece of data. Mistral, run locally via Ollama, steps in as an arbiter only when a source’s structure or semantics cannot be reliably determined by simple rules. For structured data, the engine analyzes a sample to work out a mapping plan, then applies it deterministically to the rest of the file — a separation that reserves generative inference for the steps where it actually adds value.
06
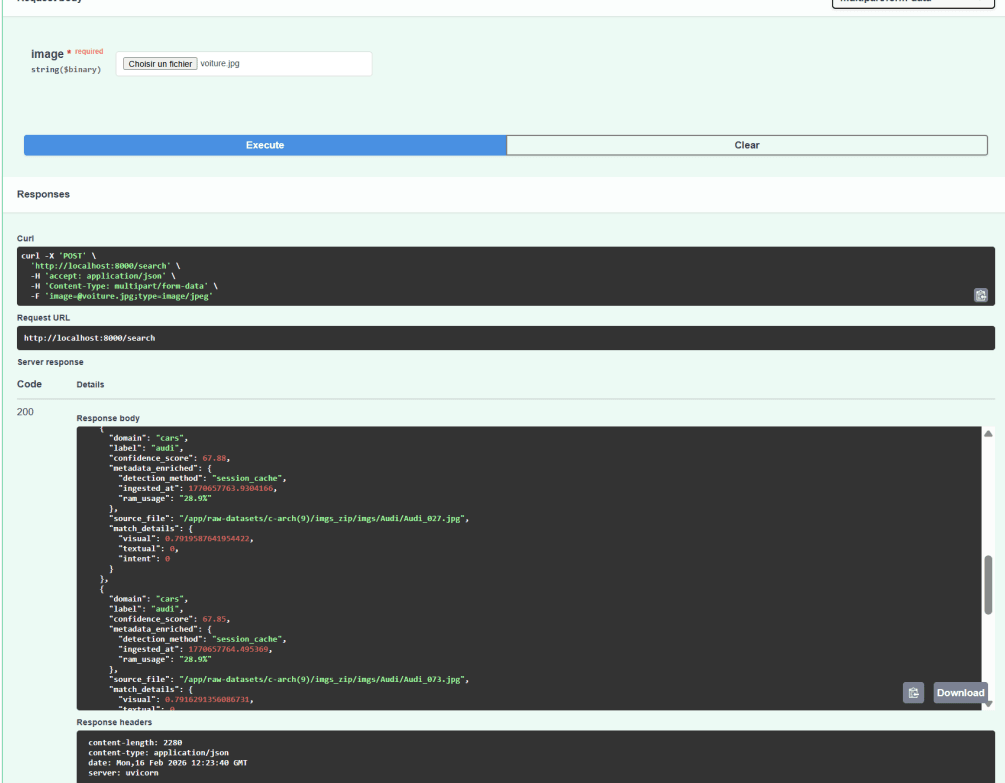
Multimodal search
A query can be analyzed for its visual similarity, its semantic closeness between image and text, and its estimated domain or intent. Results from these different passes are then merged, deduplicated, and ranked using a confidence score — an approach that handles ambiguous visual queries without relying on a single similarity measure.
07
Robustness
Several mechanisms let the engine run beyond a simple demo notebook.
- Memory usage monitoring and adaptive batch processing
- Automatic pausing when resources become too constrained
- Write retries on temporary locks
- Environment validation before launching the pipeline
- Reproducible containerized deployment
08
Validation
The engine was evaluated with large-scale ingestion scenarios and search tests, on datasets representing more than 20 GB of heterogeneous data and around 100,000 images, complemented by structured and document files. Trials covered both CPU and GPU environments.
- RAM / VRAM consumption
- Ingestion time and resuming an already-indexed corpus without full reprocessing
- Search latency and result relevance
- Robustness on queries absent from the indexing datasets
09
End-to-end chain
SmartSearch links multimodal ingestion, vector storage, vision, local semantic processing, hybrid search, and result delivery into a single chain. The project focuses less on the final interface than on the technical foundation that turns heterogeneous data into contextualized, traceable results, queryable locally.